
Executive Overview
The proliferation of hyper-realistic synthetic media has created a profound crisis of trust in modern digital ecosystems. As generative artificial intelligence advances at an exponential rate, bad actors can now produce manipulated video content—commonly known as deepfakes—that is virtually indistinguishable from authentic footage to the human eye. This capability poses severe threats to global security, democratic elections, financial institutions, and personal reputations.
Traditional countermeasures, heavily reliant on conventional digital computing architectures, are rapidly approaching a technological wall. State-of-the-art deepfake detectors demand staggering amounts of computational power, often requiring hundreds of billions of floating-point operations per video. Because these digital systems process media sequentially—analyzing one video file after another—the sheer volume of daily uploaded content creates severe bottlenecks, skyrocketing energy demands, and debilitating latency. Furthermore, conventional AI models remain highly vulnerable to adversarial evasion techniques, where malicious actors introduce subtle, calculated digital perturbations designed to trick the software into misidentifying synthetic material as genuine.
In response to this looming technological crisis, a pioneering team of researchers at the University of California, Los Angeles (UCLA) has developed a revolutionary hybrid digital-optical processor. Detailed in their landmark study, "Scalable, Energy-Efficient Optical-Neural Architecture for Multiplexed Deepfake Video Detection," published in the journal eLight, this groundbreaking technology harnesses the physical propagation of light to identify manipulated media.
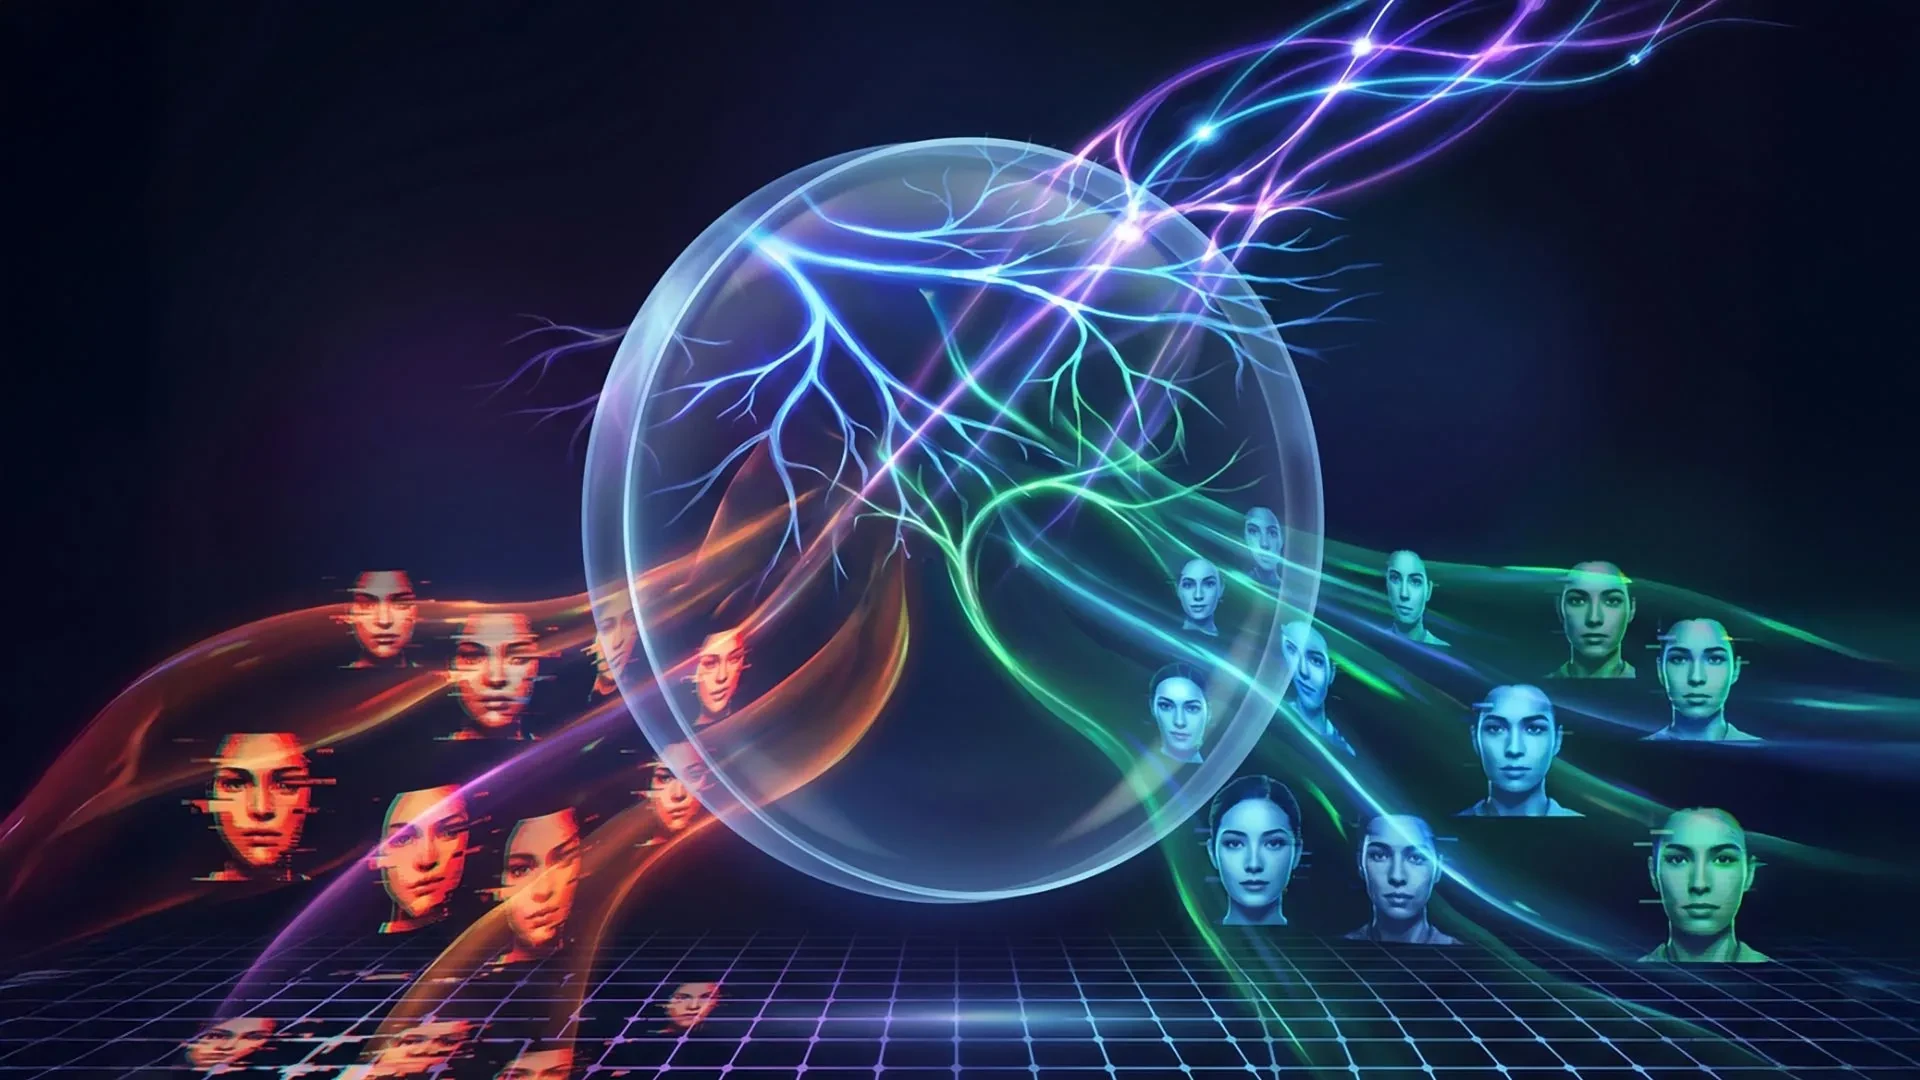
Led by Professor Aydogan Ozcan, alongside co-lead researchers Parnian Ghapandar Kashani and Dr. Shiqi Chen from the UCLA Electrical and Computer Engineering Department, the Bioengineering Department, and the California NanoSystems Institute, the innovation bypasses traditional digital processing limitations. By executing complex neural network computations through the physical diffraction of light waves, the UCLA system can analyze 15 or more video streams simultaneously in a single optical pass. Achieving nearly 98% accuracy while offering inherent resistance to adversarial tampering and exceptional energy efficiency, this optical-neural processor heralds a paradigm shift in the ongoing battle against synthetic disinformation.
Detailed Chronology and Technical Mechanics
To understand the magnitude of the UCLA breakthrough, one must examine the fundamental architectural differences between traditional electronic computing and optical computing. For decades, the digital computing paradigm has relied upon silicon-based microprocessors executing instructions sequentially or via parallel multi-core architectures. While immensely flexible, this approach scales poorly when confronted with the continuous, multi-gigabyte data streams characteristic of modern global video consumption.
The Hybrid Digital-Optical Pipeline
The UCLA research team conceived a multi-stage hybrid pipeline that strategically divides the labor between digital encoding and optical processing. Rather than forcing raw video files through a power-hungry digital neural network from start to finish, the system utilizes a streamlined, lightweight digital encoder as its initial gatekeeper.
- Digital Feature Extraction: As each video enters the system, the lightweight digital encoder rapidly extracts compact, highly informative representations of the footage. These features encompass critical spatial, spectral, and temporal dimensions—the underlying mathematical signatures that differentiate authentic human motion and texture from artifacts generated by artificial intelligence.
- Optical Wavefront Modulation: Once these features are encoded, the digital system transforms the data into a specific phase pattern. This pattern is subsequently displayed onto a programmable spatial light modulator (SLM), a device that alters the phase of a laser or visible light beam.
- Free-Space Optical Propagation: The resulting optical wavefront then travels physically through a free-space-based, passive optical decoder. Here, the heavy lifting of the neural network inference occurs not through electrical currents moving across silicon transistors, but via the natural, instantaneous wave interference and diffraction of light traveling through space.
- Authenticity Scoring: At the terminus of the optical decoder, a matrix of paired optical detectors captures the outgoing light field, directly translating the physical light intensity into an immediate authenticity score for each processed video stream.
By replacing a computationally demanding, power-intensive digital decoding network with a passive physical optical process, the UCLA system achieves massive parallelism. Multiple videos are encoded onto distinct spatial regions of the light beam, allowing them to be evaluated concurrently during a single, lightning-fast optical transit.
Supporting Context, Metrics, and Experimental Results
The validity of any novel AI architecture rests entirely upon rigorous empirical testing against established benchmarks and challenging real-world scenarios. The UCLA team subjected their optical-neural processor to a series of rigorous evaluations, demonstrating exceptional performance metrics across multiple testing parameters.
Parallel Processing Capacity and Precision
In initial experiments utilizing visible light, the optical processor successfully examined 15 distinct videos sourced from the Celeb-DF dataset simultaneously during a single optical pass. The system achieved a remarkable average detection accuracy of 97.79%, underpinned by an extraordinary sensitivity rate of 99.86% and a specificity rate of 95.72%.
In the context of security and content moderation, high sensitivity is paramount. Sensitivity measures the system’s ability to correctly identify manipulated or synthetic videos. A sensitivity rate of 99.86% translates to an average false-negative rate of approximately 0.14%. This means that out of thousands of screened videos, a negligible fraction of deepfakes slipped past the system undetected.
Seeking to test the limits of their architecture, the researchers scaled the system’s multiplexing capacity to process 18 video streams simultaneously in a single optical pass. Remarkably, even under this increased data load, the average detection accuracy remained exceptionally high at 96.13%, proving the scalability and robust throughput of the optical approach.
Scaling Performance via Passive Diffractive Layers
One of the most innovative aspects of the UCLA architecture is its capacity for physical depth expansion. The research team discovered that the processor’s analytical power could be significantly amplified by increasing the physical depth of its passive optical decoder—specifically by introducing additional optimized passive diffractive layers—without driving up electrical energy consumption or inference latency.
When researchers integrated two optimized passive diffractive layers into the system and challenged it with more sophisticated, hard-to-detect deepfake manipulations, the overall detection accuracy jumped by approximately 6.8%.
These phase-only diffractive layers are manufactured as passive, static optical structures. They perform complex mathematical calculations purely through the physical diffraction of light as it passes through their microscopic surface topographies. Crucially, because these layers are passive, they require zero additional electrical power while the system performs real-time inference. This completely upends the traditional scaling model of digital AI, where adding layers to a deep neural network triggers exponential surges in power consumption and cooling requirements.
Confronting Next-Generation Threats: Google VEO-3 and Adversarial Resilience
As generative AI models evolve, older detection systems often become obsolete. Early deepfakes were frequently betrayed by glaring visual artifacts: unnatural blinking patterns, blurring around facial boundaries, lighting inconsistencies, and unstable skin textures. Modern generative models, however, produce hyper-realistic synthetic media that largely eliminates these crude digital footprints.
Testing Against Advanced Generative Models
To ensure their optical processor was not merely overfitting to legacy datasets, the UCLA team challenged the system with advanced synthetic videos produced using Google’s VEO-3 model. These newer generative systems create footage that lacks the traditional artifacts of older deepfake software, making them formidable targets for conventional detectors.
Following minimal fine-tuning, the optical processor achieved an impressive 94.80% overall accuracy and a 97.61% sensitivity rate when evaluating previously unseen VEO-3 generated videos. These results indicate that the optical-neural approach possesses the adaptive flexibility required to stay relevant as generative video technology continues its rapid maturation.
Inherent Resistance to Adversarial Attacks
Beyond raw accuracy and throughput, the UCLA architecture introduces a profound security advantage: resilience against malicious evasion attempts.
In digital AI systems, bad actors frequently launch "adversarial attacks." In a black-box attack, an attacker probes a detector repeatedly to map its vulnerabilities, subsequently crafting subtle, malicious alterations to a deepfake video that cause the AI to classify it as authentic. In a white-box attack, the adversary possesses complete knowledge of the model’s digital architecture, weights, and parameters, allowing them to construct mathematically guaranteed bypasses.
The UCLA optical processor mitigates these vulnerabilities through its foundational physics. Because a significant portion of the inference calculation occurs via physical light diffraction through proprietary, static optical structures, the core parameters of the model are physically embedded within the hardware.
These parameters cannot be easily inspected, measured, copied, or reverse-engineered by an external digital attacker. Without access to the precise physical topography of the diffractive optical layers and the exact optical alignment, malicious actors cannot reliably simulate the detector in software to craft targeted adversarial workarounds. Furthermore, the system demonstrated robust operational reliability when subjected to common real-world degradations, including image noise, compression artifacts, blur, and experimental optical misalignments.
Official Statements and Future Outlook
The implications of integrating optical computing with artificial intelligence extend far beyond anti-deepfake technology. As computing demands outpace the physical limits of Moore’s Law and silicon scaling, researchers are increasingly looking to photonics—the science of generating, controlling, and detecting photons—as the foundation for next-generation computing architectures.
A Scalable First Line of Defense
Crucially, the UCLA team does not envision their optical processor as a standalone replacement for every existing digital algorithm. Instead, the architecture is intentionally designed to serve as a high-throughput, energy-efficient first layer of defense in a tiered detection ecosystem.
[ Massive Video Inflow ]
         │
         ▼
┌─────────────────────────────────┐
│ UCLA Optical-Neural Processor   │ (High Throughput, Parallel Screen,
│ (Simultaneous Multi-Stream Scan)│  Near-Zero Latency, Low Energy)
└────────────────┬────────────────┘
         │
         ├───> [ Verified Authentic ] ───> Approved / Released
         │
         └───> [ Flagged Suspicious ] ───> [ Heavy Digital AI Models ]
                                           (Deep Forensic Analysis)
In a practical deployment scenario, massive volumes of streaming video content—such as uploads to social media platforms, live-streamed feeds, or enterprise communication channels—would first pass through the parallel optical processor. Because the optical system screens 15 or more streams concurrently with minimal power draw, it can instantaneously filter out the vast majority of clean, authentic media.
Only content flagged as suspicious by the optical processor would be routed downstream to computationally heavy, resource-intensive digital neural networks for deep forensic verification. This hybrid pipeline optimizes resource allocation, dramatically slashing the computing infrastructure costs and carbon footprint required to police global digital media.
Collaborative Innovation and Broader Applications
The breakthrough published in eLight represents the culmination of intensive collaborative research within UCLA’s academic community. Co-lead authors Parnian Ghapandar Kashani and Dr. Shiqi Chen worked alongside principal investigator Professor Aydogan Ozcan, uniting expertise across electrical engineering, bioengineering, and nanotechnologies at the California NanoSystems Institute (CNSI).
Looking forward, the research team believes this hybrid optical-neural framework can be scaled and adapted for a wide array of security-critical AI applications. Beyond social media content moderation and media authentication, high-speed optical processors could soon play vital roles in secure automated surveillance, defense intelligence, real-time broadcast verification, and enterprise cybersecurity.
As society navigates an era where seeing is no longer necessarily believing, innovations like UCLA’s optical-neural processor provide a vital glimmer of hope. By fusing the speed and limitless bandwidth of light with the analytical power of artificial intelligence, researchers have forged a powerful new shield to protect the integrity of human communication in the digital age.